Every Depotex feature works the same on one node or many. What changes is how the nodes coordinate. On Kubernetes, the Helm chart runs the server as a StatefulSet and scales it with backend.replicas: see Docker & Kubernetes.
| Single node | Cluster | |
|---|---|---|
| License | Standard or higher | Pro or higher |
| PostgreSQL | Required | Required, shared by all nodes |
| Redis | Optional | Required, shared by all nodes |
| Storage | Any backend | S3, MinIO, Azure, or a shared volume |
| Nodes | 1 | Up to the license limit |
1. Redis
Give Redis as a URL in the setup wizard, the unattended setup file (cache.redis_url) or the recovery page. Depotex supports three kinds:
| Kind | URL |
|---|---|
| One server | redis://:password@redis.internal:6379/0, or rediss:// for TLS |
| Sentinel group | redis+sentinel://:password@s1:26379?master_name=mymaster&addr=s2:26379&addr=s3:26379: Depotex follows the primary when Sentinel fails over |
| Redis Cluster | redis+cluster://:password@n1:6379?addr=n2:6379&addr=n3:6379: every shard is used |
- Each kind takes TLS (rediss, rediss+sentinel, rediss+cluster), a private certificate authority (ca_file=/path/ca.pem) and Redis ACL users (user:password@).
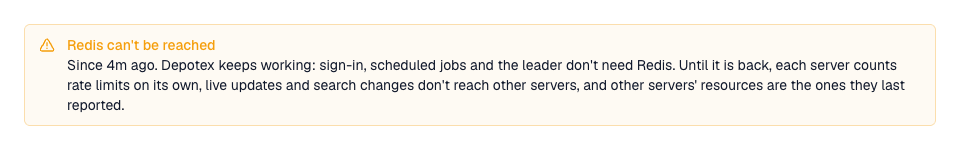
- Redis coordinates; PostgreSQL keeps the records. If Redis becomes unavailable, Depotex keeps working: each server counts rate limits on its own, sign-in keeps working (sessions are kept in PostgreSQL, so a sign-out made while Redis is away still holds when it returns), scheduled jobs keep running once per cluster and a leader is still elected (both are coordinated in PostgreSQL), live updates (the alert bell, job status) and search changes still reach every server through PostgreSQL, and changes reach other servers within 30 seconds instead of at once. It logs one warning when Redis goes and one message when it returns. A server that starts while Redis is down starts anyway, after waiting 10 seconds for it, and connects once Redis answers; the recovery page lists an unreachable Redis as a warning.
- A failover can lose the last few writes to Redis; results stay correct because PostgreSQL holds the records.
2. Database connections
Each server opens up to pool_max_conns connections to PostgreSQL (by default 4, or the number of CPUs if that is more). Set it in DATABASE_URL, for example postgres://depotex:…@db:5432/depotex?pool_max_conns=25. In a cluster every server opens its own, so keep the number of servers × pool_max_conns, plus room for maintenance, under PostgreSQL's max_connections (100 by default).
3. Read cache
Each server keeps what most requests look up, such as spaces, repositories, roles, access grants, upload rules, quota limits and repository settings, in its own memory. PostgreSQL tells every server the moment one of these changes, from any server, and each server also checks for changes every second, so a change applies everywhere almost at once. Redis is not needed for this, and it works the same when Redis is down.
Whether an API token is valid, sessions and storage used against a quota are never kept in memory: revoking a token or disabling a person takes effect on every server at once. A server that can't check for changes for three check intervals (3 seconds by default) stops using what it kept and reads the database until checking works again.
| Variable | Default | Meaning |
|---|---|---|
| READ_CACHE_ENABLED | true | false turns the read cache off on this server: every request reads the database. Use it if you suspect a server is showing an old setting. |
| READ_CACHE_CHECK_INTERVAL | 1s | How often a server checks for changes in case it missed a notice (up to 1m) |
| READ_CACHE_MAX_AGE | 5m | The longest a server uses something it read, whatever the checks say (1s to 1h) |
| READ_CACHE_MAX_ENTRIES | 20000 | How many items each kind of lookup keeps per server |
4. Clustering
Nodes register themselves, send heartbeats, and elect a leader. Settings → Clustering lists every node in a table: status (the leader has a crown), health, name and machine ID, version, CPU, memory, uptime and last heartbeat. Cluster health above the table sums up every server's latest self-check, with View server for each thing that needs attention. Select a node to open its identity, resources and recent events below its row, and rename it with the pencil (Pro). A node that stops responding gets a red notice above the table saying how many heartbeats it missed, with View node. How clustering works and the environment variables that tune it are explained below the table.
| Status | Meaning |
|---|---|
| active | Running. |
| draining | Shutting down: finishing its work before it stops. |
| left | Shut down cleanly. Removed from the list after a day (CLUSTER_DEAD_NODE_TTL); a server that starts again with the same identity becomes active again. |
| dead | Stopped sending heartbeats (30 seconds by default, longer for the leader) without shutting down cleanly. Also removed after a day. |
When the server showing the page can't reach Redis, a notice above the table says since when, and what still works. Each node's CPU and memory come live over Redis; until it is back, other nodes show the values they last saved (every minute), and their details say when that was. The system check lists Redis as a warning on each server that can't reach it.